The problem: it sounds good but leaves no trail
A systematic review is not a summary of what has been published on a topic. It is a method: you define a question, search in a documented way, decide with written criteria which studies get in and which don't, and keep a record of everything. PRISMA 2020 is the guideline for reporting that process (how studies are identified, selected and included), and PRISMA-S extends it to the search itself.
The first problem the author wanted to attack is how fragile a review is when a single model does it, whoever makes the model. A model summarizes, compares and proposes lines of argument very well, but that is not a serious review. If the process leaves no trail of the search, the inclusion criteria, the reasons for exclusion, proof that someone read the full text and a verifiable closing, the result can sound good and be methodologically weak.
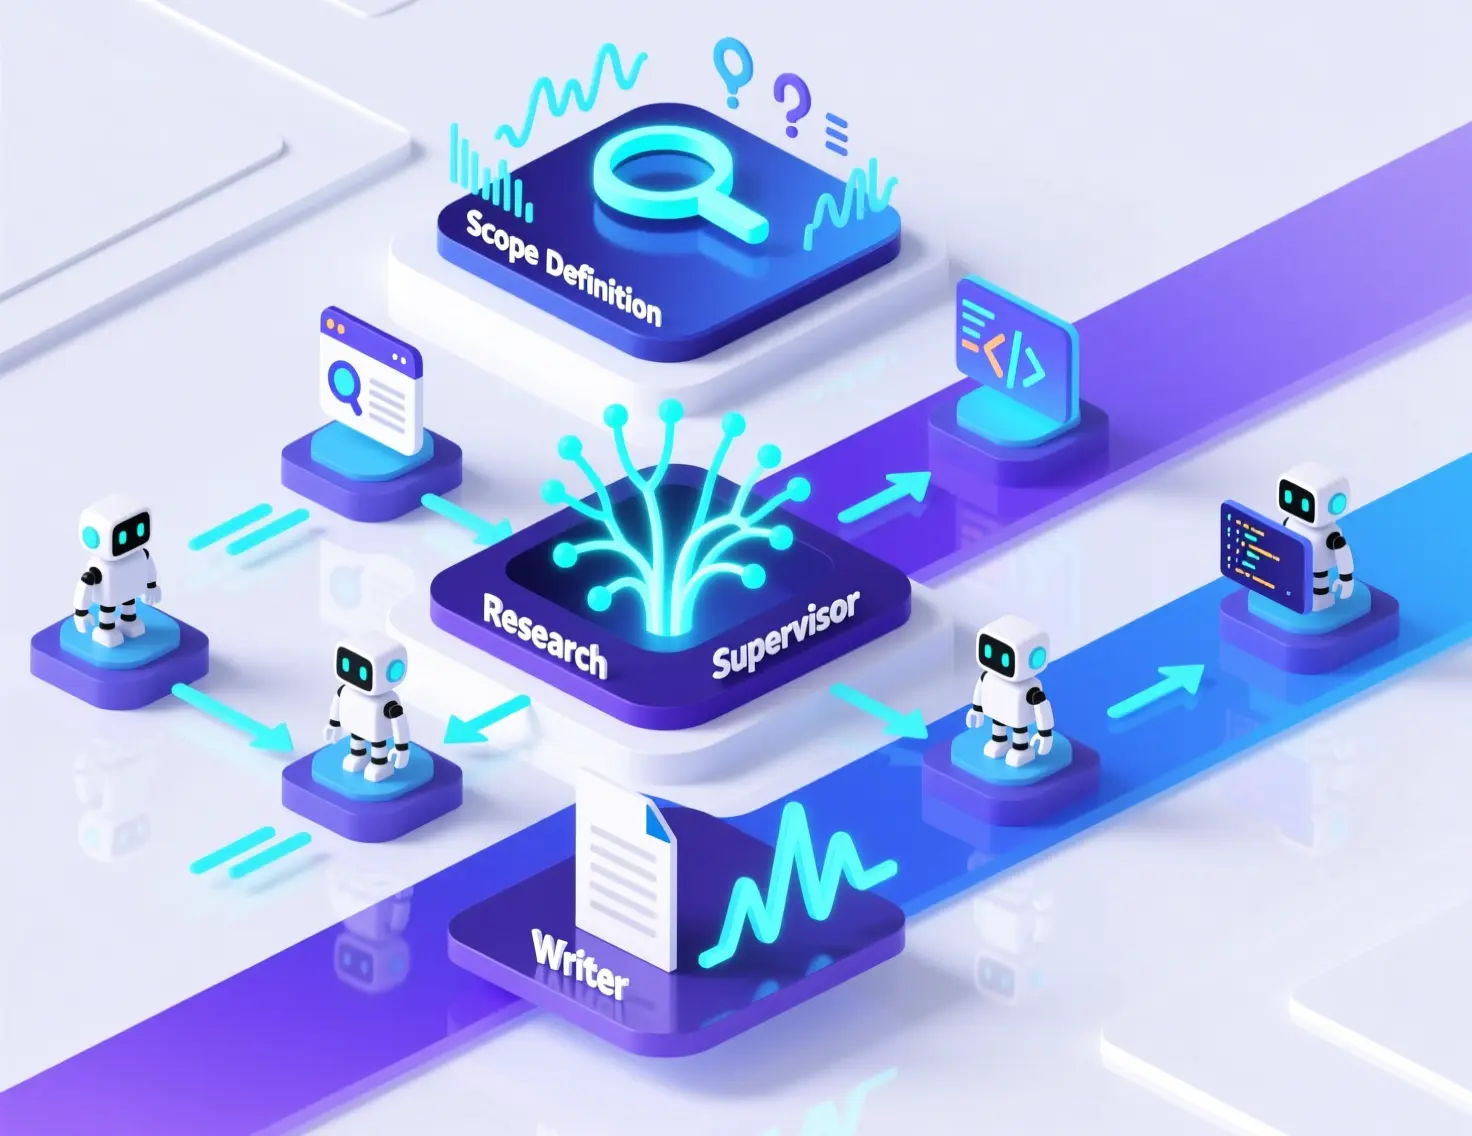
The second problem is operational. A review is not solved with one call to the model. It needs a protocol, bibliographic acquisition, a DOI audit, screening, PDF retrieval, full-text reading, extraction, figures, manuscript writing, cross-review, packaging and syncing. If all of that lives only in the memory of a conversation, the system is fragile by definition.
That is why the system separates state, process and persistent artifacts. The line that sums it up: what matters is not that the agent «remembers», but that it reads again what it left written.
Before getting into it, the author adds a disclaimer: no interest in the university debate about whether these systems should be used; the point is only to show how this one is built inside so others can replicate or improve it. And a warning: the packaged agent is not released yet. That, the author says, will come in another article.
The six rules
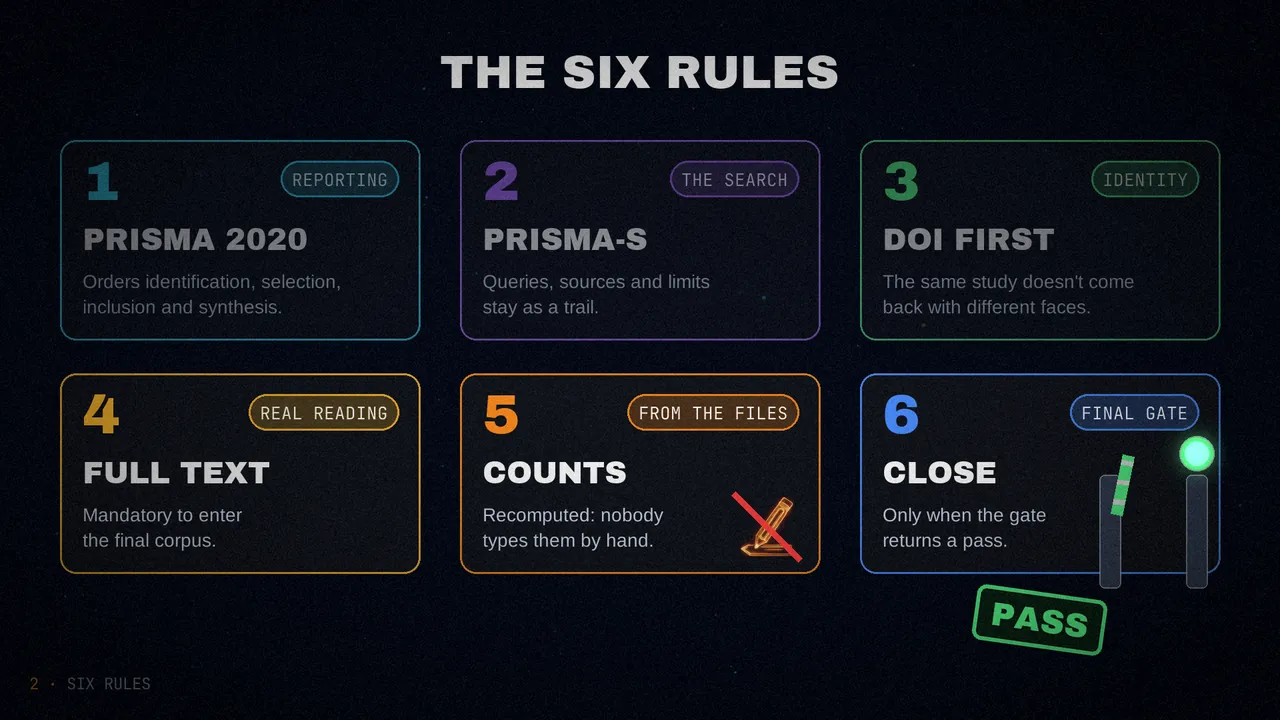
The system is not built around the question «what can an agent do in this research?», but around another one: «what minimum conditions must a review meet for me to trust it?». The answer is six rules:
- PRISMA 2020 as the reporting framework.
- PRISMA-S as the framework for search transparency.
- DOI-first: whenever it exists, the DOI (the unique identifier of each publication) is the key for each study.
- Mandatory full text for the final corpus.
- Counts are recomputed from the real files; nobody types them by hand.
- Editorial closing only when the final gate returns PASS, not on the subjective feeling that «it's good enough».
These rules live in a file, the base skill prisma-systematic-review/SKILL.md, which works as an operational and methodological contract. The author insists on this: in many agent systems the interesting part sits in invisible prompts. Here the methodology is something you can version and audit.
The rule that costs the most tokens is the fourth. It demands readable full text for final inclusion, and a model that can read that kind of document well. An abstract helps to discard quickly, but it is not enough to declare that a study belongs to the corpus. In the author's words, it is a methodological boundary, not a style preference.
The architecture: four layers
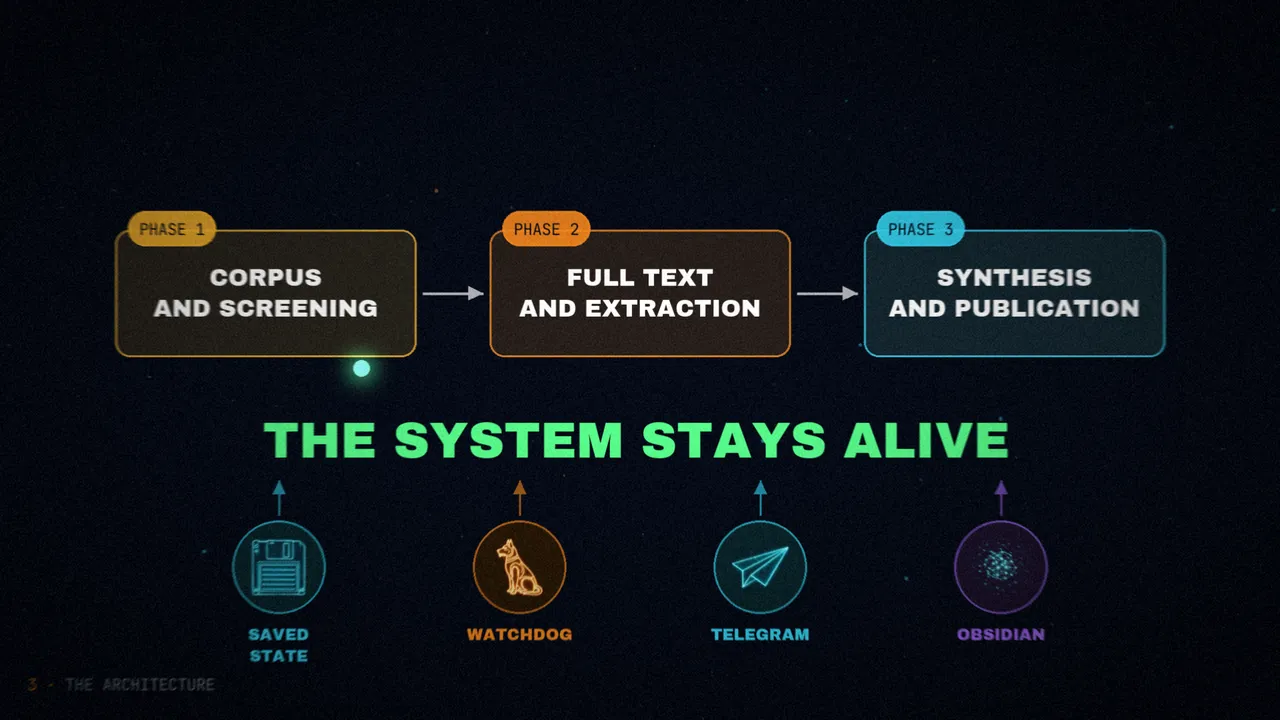
The system is built with Hermes (Hermes Agent, according to the article's architecture figure) and rests on four layers:
- A minimal surface on Telegram. The author doesn't want operations to depend on a custom interface. Reviews are launched and checked with commands such as
/prisma_systematic_reviewand/prisma_status. - The runtime in Docker, with two services:
hermes-agentruns the gateway and the main work, andhermes-prisma-watchdogmonitors live reviews and resumes phases when it detects they have stalled. - The model policy. The primary model is Qwen 3.6, served by NaN Builders. If it fails, there is a fallback chain on Ollama Cloud: DeepSeek v4-pro, Kimi K2.6, Qwen3-coder and Gemma4. It all lives in a
config.yamlwith its parameters. - Orchestration, with three scripts:
complete_review.py,publication_autopilot.pyandpublication_gate.py.
There is another layer that usually stays hidden: the skills. The author's installation has ten local research skills, and on the road to a publishable review five do most of the work: systematic review, status, academic review, integrity and revision roadmap. The underlying idea is that the architecture is not one super agent that does everything, but specialized layers with small contracts. That, the author says, keeps it maintainable for this use case.
According to the article's figures, the work is organized in three phases: corpus and screening; full text and extraction; synthesis and closing.
How a review starts
One of the most useful ideas in the article: a review gets biased earlier at intake than later in the discussion. So the system forces you to freeze, as soon as possible, the question, the time window, the admissible type of study, the target number of final studies, the inclusion and exclusion criteria and the editorial framework. If the topic starts as «let's see what comes up», the rest of the system only automates ambiguity.
That phase leaves a trail from the first minute, in three files:
protocol/intake.md: the question and the scope.protocol/eligibility-criteria.md: the inclusion and exclusion criteria.protocol/search-strategy.md: the search strategy.
What matters is not only that they exist, but that someone else can open them and check whether the bias was born in the question, in the search or in the interpretation.
There is a detail the author likes to mention. If there is no specific target journal, the system falls back to a generic mode (generic-common-core), a template that would pass a first filter. That decision affects the LaTeX template, the editable package and the tone of the closing. It is a way of not pretending the work is aligned with a journal that hasn't been chosen yet.
Four commands, four uncertainties
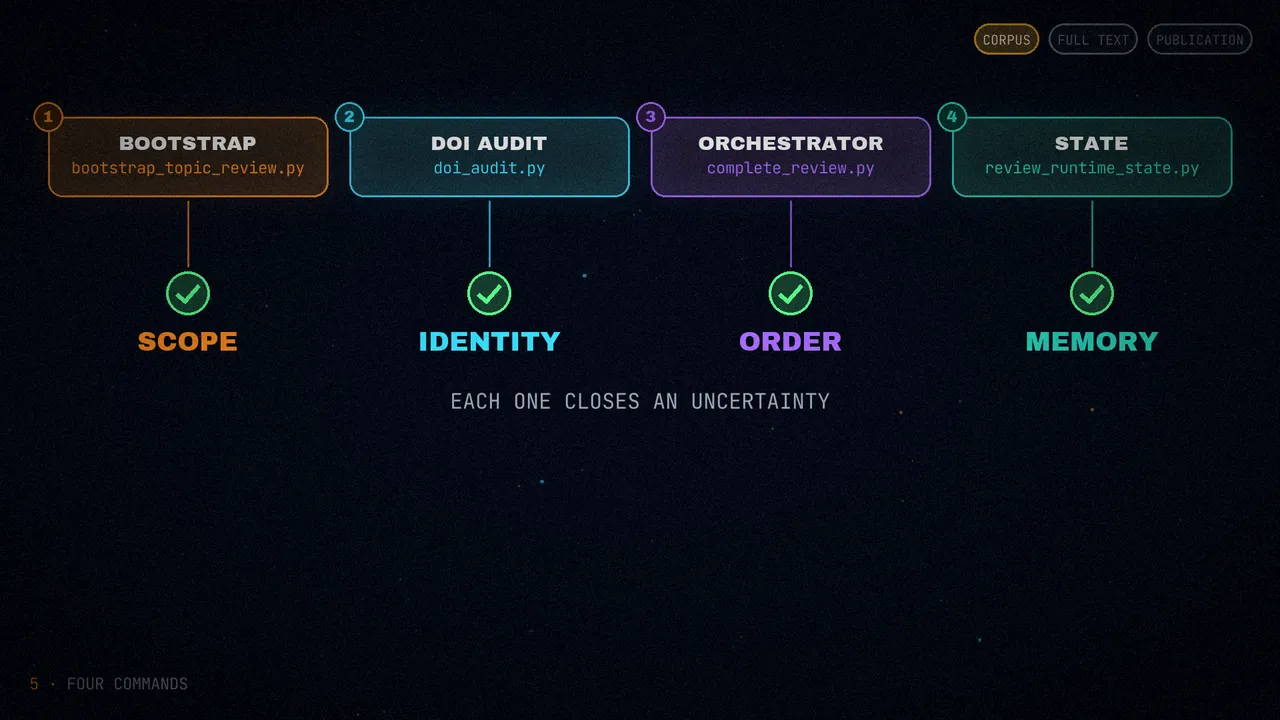
This is where the review stops being an intention. The question, the unit of analysis, the time window, the criteria and the quality threshold are fixed in files that condition everything that follows. Four pieces do it, and each one closes a different uncertainty:
| Piece | What it fixes | What it does |
|---|---|---|
bootstrap_topic_review.py | The scope | It doesn't just create folders: it materializes the starting point (the intake.md, the search strategy and the project structure). If the corpus later turns out biased, you can go back to that origin and see where the problem was born. |
doi_audit.py | The identity of the corpus | It separates records with an identifiable DOI, duplicates and ambiguous ones. It avoids one of the most common errors: believing there are more studies than really exist, or not knowing why a paper was merged or discarded. |
complete_review.py | The order of the process | It governs the whole sequence: acquisition, screening, full-text retrieval, extraction and the jump to the editorial layer. No extraction if the corpus isn't fixed, no study accepted without full text, no publication if intermediate artifacts are missing. |
review_runtime_state.py | The operational memory | It keeps the state outside the conversation: what is done, what is missing, what is blocked and which files support each step. If the review is interrupted, the system reads it again and continues. |
The methodological boundary is written down before the first record is imported. From then on, the system no longer tries to guess which review the author wants: it runs the one that was specified.
From four sources to a DOI-first universe
The system queries several sources because none is enough on its own: OpenAlex, Crossref, Semantic Scholar and arXiv, with direct HTTP calls. The result is not «a search in the abstract», but a set with a technical trail, spread over five files:
searches/search-log.csv: the query, the source, the date and how many records came back.records/master-records.csv: the raw universe, normalized.records/doi-index.csv: the canonical key of each study, by DOI.records/duplicates.csv: the collisions detected.records/missing-doi.csv: what cannot be resolved by DOI.
When a record has no DOI, the system generates a stable hash-based identifier for it (a RID). That way the same paper, arriving from two sources with its title written two ways, counts once. According to one of the article's figures, this approach «reduces noise, lowers cost and improves reliability»; that is the author's claim, not a measurement.
At this point, the author says, the review stops being a collection of searches and starts to look like a document base.
How it decides: OK, KO or needs more
The inclusion and exclusion logic is not a magic algorithm, and it is not asking a model «does this look relevant?». It is a sequence of four layers:
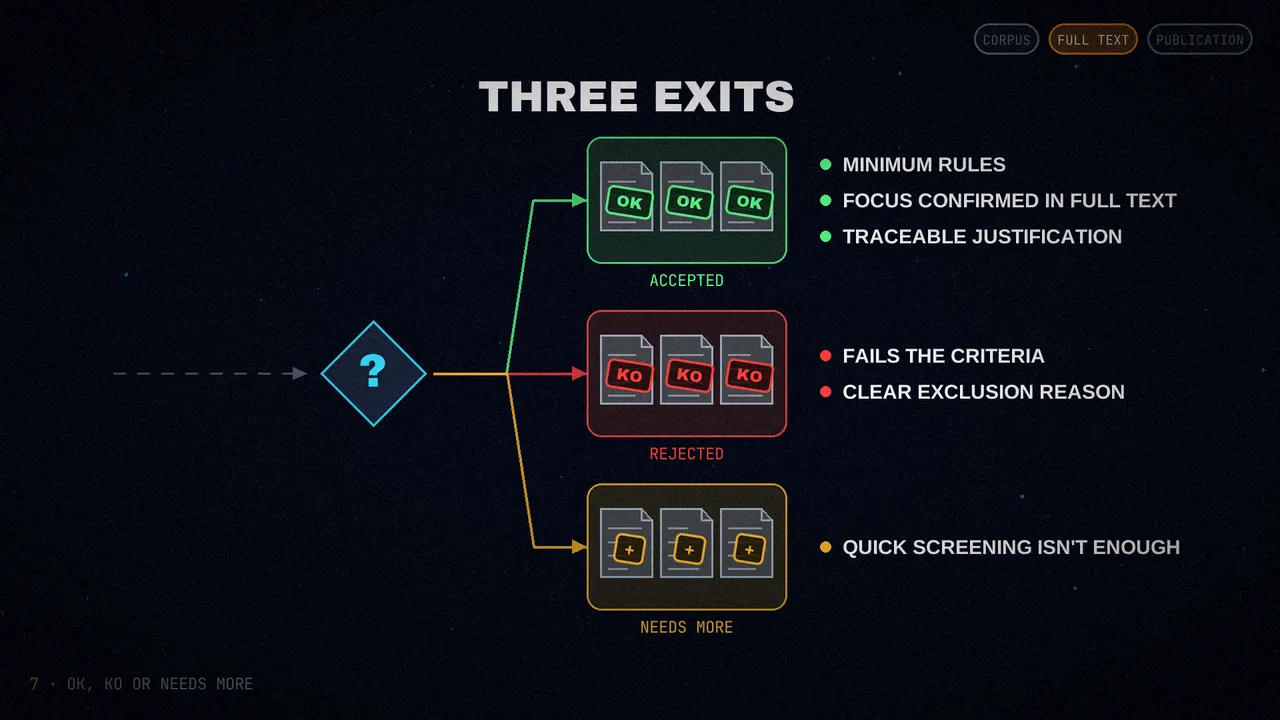
- Minimum rules. The most visible one is a minimum threshold of useful text: if the full text doesn't reach it, there is no basis for final inclusion. The article's text gives no number; one of its figures sets it at 4,000 useful characters.
- Model-assisted decision. The model classifies and justifies.
- Canonicalization. A function normalizes the variants (
include,include_ft,exclude, «excluido», «excluir»,maybe) into a consistent set of decisions. - Audit with recomputation. The counts in the PRISMA diagram are not typed by hand: they are recomputed from those normalized decisions.
With that, each study ends in one of three exits:
It passes the minimum rules, confirms the focus in the full text and leaves a traceable justification in a CSV.
It fails those criteria or has a clear reason for exclusion.
Quick screening is not enough to decide.
For the author, this logic is closer to structured appraisal tools such as ROBIS or AMSTAR 2 than to a simple relevance ranking. That is an opinion about the design, not a formal equivalence.
Deep extraction
Knowing that a paper is «experimental» is not enough. The author wants to know which systems it names, which benchmark it uses, which sample it describes, which variables it employs, which method it reports and which theory it stands on. All of that goes into extraction/extraction-table.csv, with fields such as work_type, empirical_type, models_or_systems_studied, benchmark_dataset_or_corpus, dependent_variables or theoretical_framework.
When the first extraction falls short, refresh_extraction_depth.py comes in: it rereads the text extracted from the PDF and forces a deeper layer. It solves a problem the author says came up several times: papers that after a first pass were labeled only as «experimental study», when the full document did offer names, scales and metrics. The author flags this as very important for anyone building their own system.
Each study is organized in four blocks:
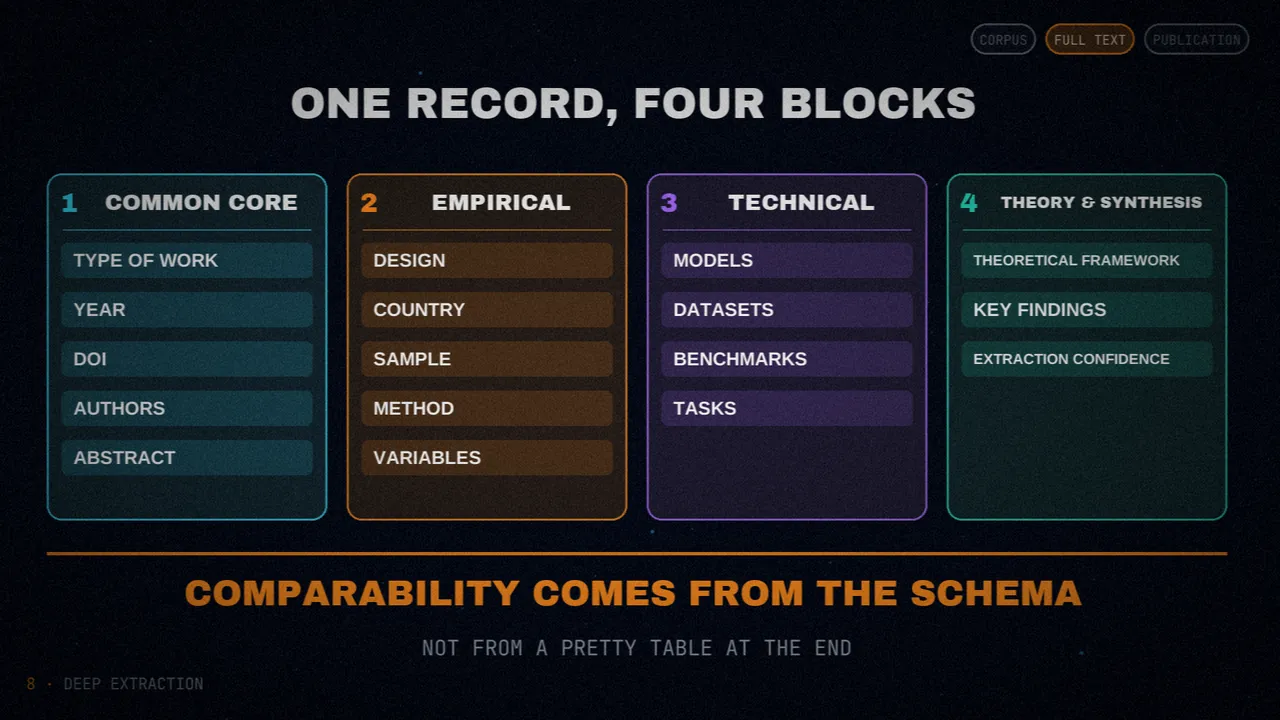
The conclusion of this part: comparability across studies comes from the extraction schema, not from a pretty table at the end.
Figures and visual evidence
In many topics, a figure concentrates the architecture, the experimental design or the relations between concepts that the abstract doesn't capture. So the system has an explicit layer of visual evidence, with models that can see and process images.
The key script, prepare_paper_figures.py, separates three things that are easy to mix up:
- Scientific figures extracted from the PDFs (
figures/extracted/). - Page renders for support and diagnosis (
figures/page-renders/). - Own figures, generated for the manuscript.
Without that separation, a full rendered page can be mistaken for a reusable figure. Traceability lives in a manifest, a catalog and a ranking (figures/manifest.csv, figure-catalog.md and figure-ranking.csv). Own figures carry a signature (in this case, 686f6c61) to tell them apart from those of the corpus: mixing someone else's evidence with your own visual synthesis is, the author says, bad methodological practice and bad editorial practice.
From corpus to manuscript
Once the corpus is consolidated, the challenge shifts from documentary to editorial. The central piece is publication_audit.py: it rebuilds sections, cleans up inconsistencies, normalizes citations and references, integrates tables and figures, detects obvious gaps and generates the manuscript. It leaves three versions of the same document in paper/manuscript/:
publication-ready.md: the editable version.publication-ready.tex: the LaTeX output, to keep working in an academic setup.publication-ready.pdf: the compiled version, ready to circulate.
On top of that come the BibTeX bibliography (references.generated.bib) and the generic template main-common-core.tex when there is no target journal.
Here the author imposes what are described as personal quirks: every relevant study must have more than a table row. The manuscript includes a short profile per study, one or two paragraphs before the compact table, and expanded blocks for discussion, theoretical implications, original contribution, conclusions and future work. «Publication-ready» is the name of the files and the author's goal; the article doesn't say that any of these reviews has been published.
Cross-review and the final gate
For the author, this is the layer that most sets the system apart from a conventional flow with several models. A manuscript is not accepted because a model wrote solid prose. It is accepted when it gets through a cumulative circuit:
- Cross-review (
publication_peer_review.py). Reviewer A runs on Qwen 3.6 and reviewer B on DeepSeek v4-pro; Kimi K2.6 is the first editorial fallback. The assignment sits in a file,reviewer-models.csv. - Integrity (
check_manuscript_integrity.py): it hunts for weak claims, inconsistencies and gaps in support. - Revision roadmap (
build_revision_roadmap.py): it turns the review into a matrix of actionable changes. - Final gate (
publication_gate.py): it checks that the required artifacts exist and that the closing is legitimate. - Autopilot (
publication_autopilot.py): it repeats the circuit until it closes or documents a real blocker.
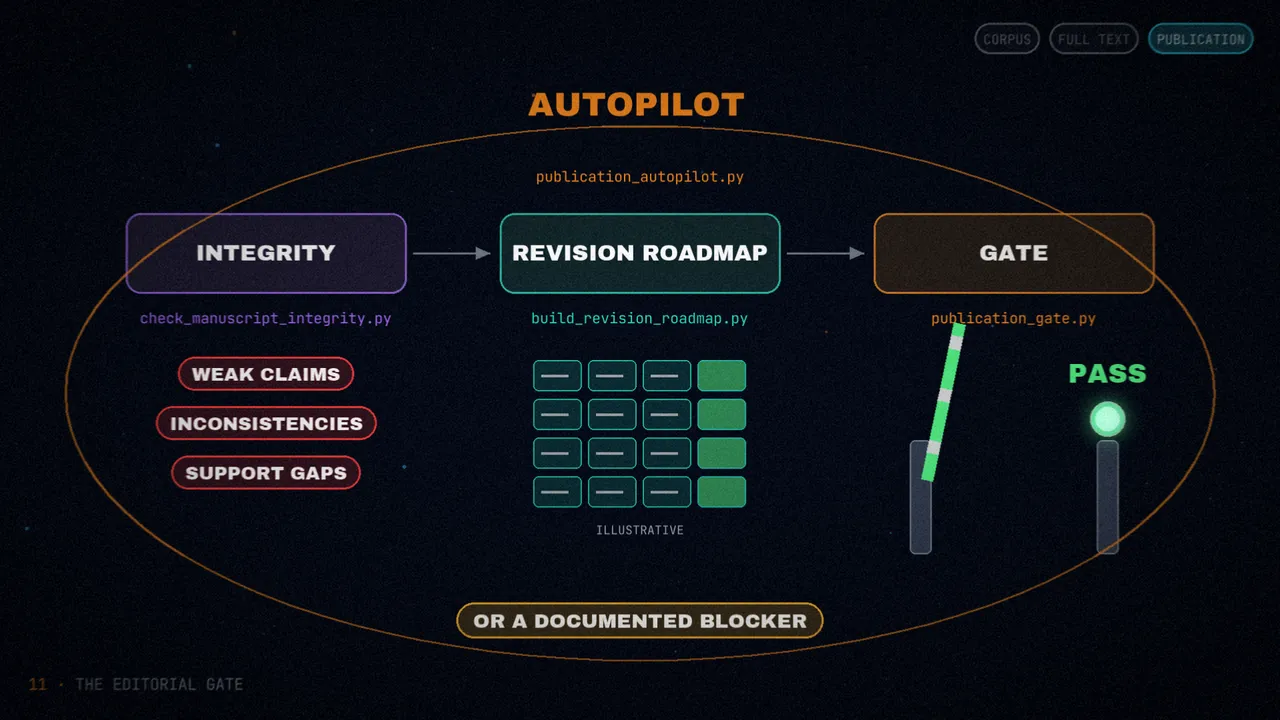
It is worth reading this precisely: the two «reviewers» are different models reviewing each other, not independent human reviewers and not a journal's peer review. What it avoids, according to the author, is one specific mistake: delivering something that looks finished when it hasn't passed the checks that justify calling it publishable.
Packages and memory outside the chat
When the gate returns PASS, the system doesn't end in a loose folder. It builds two packages, because not every reader needs the same thing: publication-package.zip, the general editorial package, and publication-latex-editable.zip, to keep editing in LaTeX.
At the same time, sync_review_to_obsidian.py syncs the review to an Obsidian vault, where a browsable version stays: study notes, overview, visual library, notes and the PRISMA trail.
Continuity doesn't depend on remembering a conversation. It depends on state files (notes/runtime-state.md and notes/runtime-state.json), on manifests, on the ZIPs and on a watchdog that knows how to reread and resume. The system's real memory is outside the chat. According to the author, from a FAIR point of view this brings the review closer to a findable, accessible and interoperable asset; the article doesn't claim it complies.
The limits the author admits
The article doesn't close pretending the system is perfect. It still depends on four things: the quality of the sources, whether the full text can be retrieved, whether the cloud models are available and whether complex figures or tables can be extracted without loss.
And even with a hardened gate, the author sees four areas to improve:
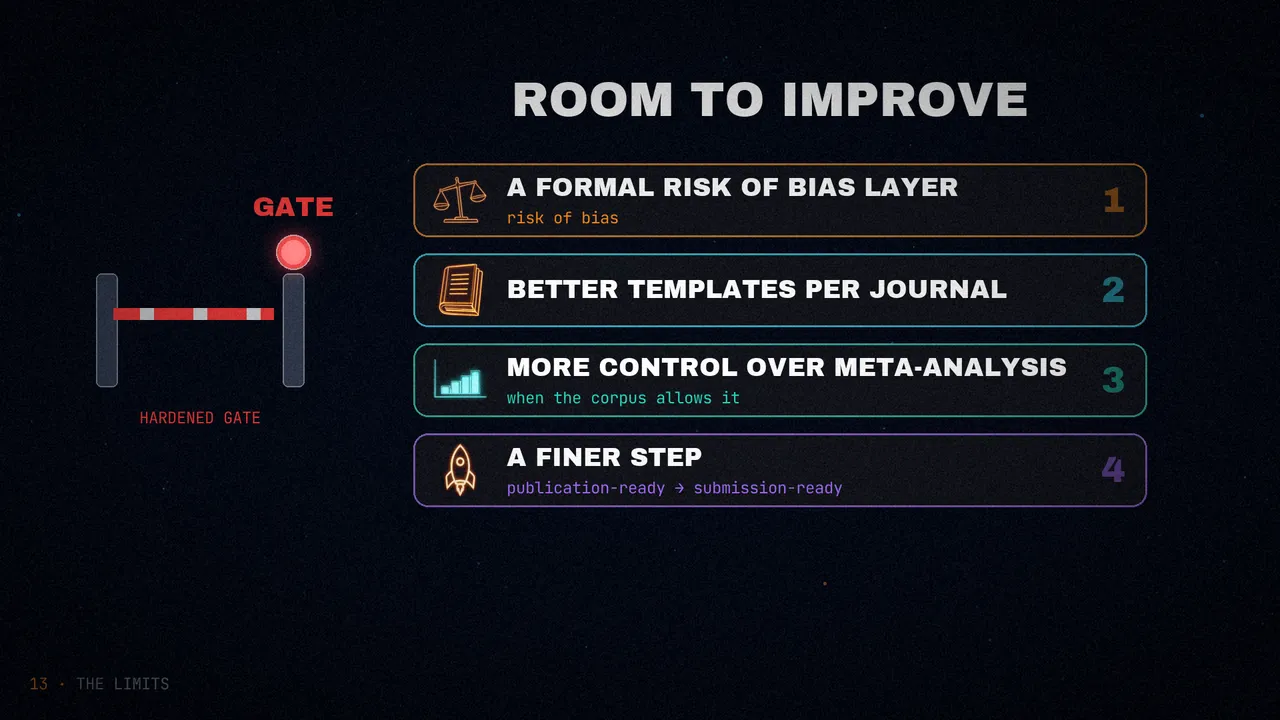
The first one is telling: a formal risk of bias layer is still missing. The author says work continues toward publishing something people can install, use and improve.
How to read this article
- It describes a design, not results. There are no figures for accuracy, time or accepted reviews. «Publishable» and «defensible» are the author's goal, not something the article proves.
- You can't install it yet. The package is not released; the author announces it for later.
- It doesn't remove bias. What it does is leave a trail so someone else can audit each decision.
- The reviewers are models. It is cross-review between different models, not independent human review.
- Models and versions (Qwen 3.6, DeepSeek v4-pro, Kimi K2.6…) are those of the author's installation, as named in the article.
In short
What I take from the article applies to any agent system, not only to scientific reviews: rules in a file instead of an invisible prompt, one file per step, memory outside the conversation, counts recomputed from the data, and a final gate that decides the closing instead of the feeling that «it's done».
A serious review leaves artifacts, not just a convincing conversation; quality is an exit condition, not an intention.
Would you trust a review made this way if you could open every file and follow every decision?
Sources
- «Cómo monto un sistema de revisión PRISMA que se audita solo con HERMES», by Entre Kaczynski y Chinaski (@686f6c61), on X (May 10, 2026; in Spanish).
- Guidelines the article cites: PRISMA 2020 (Page et al., 2021), PRISMA-S (Rethlefsen et al., 2021), ROBIS (Whiting et al., 2016), AMSTAR 2 (Shea et al., 2017) and the FAIR principles (Wilkinson et al., 2016).
- The video, on my channels: English and Spanish.